A month ago, our NAS started giving us trouble, so we had to carry out a rescue operation.
One disk in the NAS pool's first VDEV failed. When we tried to replace it with a spare, another disk in the same group started reporting unrecoverable read errors. We had to switch the entire NAS to read-only mode and start synchronizing it to Backuper, our backup machine.
Unfortunately, this took a very long time and had to be repeated several times. ZFS's recursive send-receive process is terribly poorly thought out: an interrupted transfer can't be resumed. When you're moving 22 TB of data and it stops halfway, you have a problem. Some experimental patches address this, but they only work on a single dataset, not recursively.
We eventually managed it with some manual synchronization. Almost all the data was saved; only about 72 files couldn't be read. Considering that we consistently describe the NAS as storage without backups, I think that's a good result. There were five damaged disks in the array in total, and of course we didn't put them back. After replacement, we have five spare disks ready for another failure.
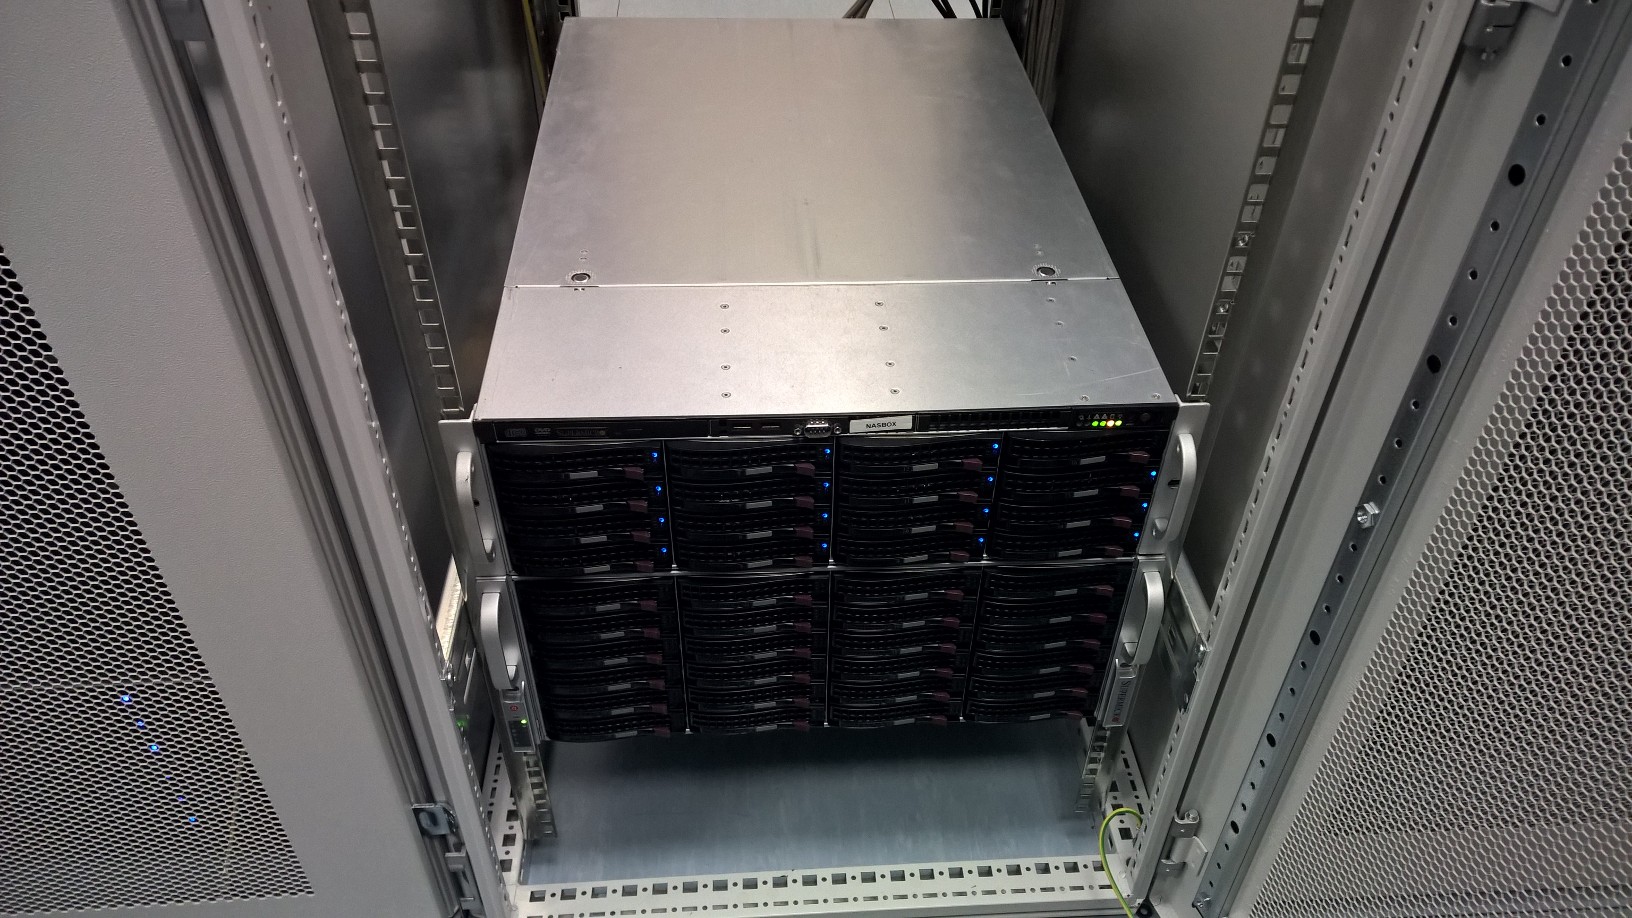
We've also added more disks to the NAS, more than doubling its usable capacity to 110 TB. We plan to move data back onto it from Backuper, whose array also needs rebuilding in a safer configuration. Since we don't want to stop making backups, we have to use the expanded NAS temporarily to migrate the backups.